LLM Tokens, Explained from Scratch
Tokens decide what an LLM costs, how much it can read, and why some text is pricier than other text.
This post has code and diagrams. It reads best on desktop or in landscape.
Every time you send a message to ChatGPT, Claude or Gemini, your text is first chopped into small pieces called tokens. Tokens decide how much the model can read in one conversation, why a huge paste can hit a limit, and, depending on the app, how quickly you reach your usage cap.
If you build with an API, they also decide what you pay: every response carries a small field like "usage": { "prompt_tokens": 142, "completion_tokens": 57 }.
Those two numbers are your bill, and they explain some surprising things, such as why the same chatbot can cost noticeably more in Korean than in English.
Those counts come from the GPT-4 tokenizer. Newer tokenizers narrow the gap, as you'll see later.
This post explains what tokens are, from scratch. You don't need any machine-learning background. If you've seen a little code, you're ready: the examples use TypeScript, with Python where it helps, and the ideas matter more than the syntax. By the end you'll know how to count tokens, predict your bill, and avoid the mistakes that waste money.
What Is a Token?
A language model can't read letters or words the way you do. Before your text reaches the model, a program called a tokenizer cuts it into small pieces. Each piece is a token.
A token is not always a word, and it's not a single character. It's something in between. Think of tokens as the syllables of machine reading:
- Common words like
helloare usually one token. - Longer or rarer words are split into several pieces, like
token+ization. - Spaces and punctuation count too, often attached to a neighbouring word, and long numbers are split into pieces as well.
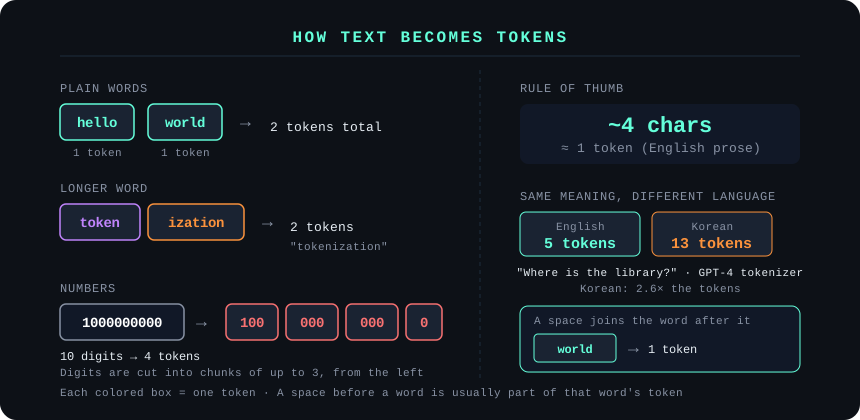
A handy rule of thumb for English: 1 token is about 4 characters, or about ¾ of a word. So 100 words is roughly 130 tokens, and a 1,000-word article is roughly 1,300 tokens. This is only an estimate, and it only holds well for ordinary English prose. Code, numbers and other languages usually take more tokens, and we'll get to why below.
Before you dump in a large block of copied text, stop and check how big it is. Long pastes are the fastest way to burn through your context window and your budget. Most chat apps have no token counter, so use the rule of thumb above (about 750 words per 1,000 tokens) or paste the text into a tokenizer tool first, like the OpenAI Tokenizer linked in "Counting Tokens in Code" below. Treat the result as an estimate for models other than OpenAI's.
Where Tokens Come From
Someone has to decide what the pieces are. Nobody does it by hand. Before the model is trained, a program reads a huge pile of text and learns the pieces on its own. The most common method is called Byte Pair Encoding (BPE), and the idea is simple:
1. Start with single characters (real tokenizers start from raw bytes, so any language works).
2. Find the two pieces that show up next to each other most often.
3. Glue them into one new piece.
4. Repeat until you have a big list of pieces, usually tens of thousands to a few hundred thousand. That list is the tokenizer's vocabulary.
When you send text, the tokenizer uses that list to cut your text into known pieces. The diagram below shows the idea with the word "lowest":
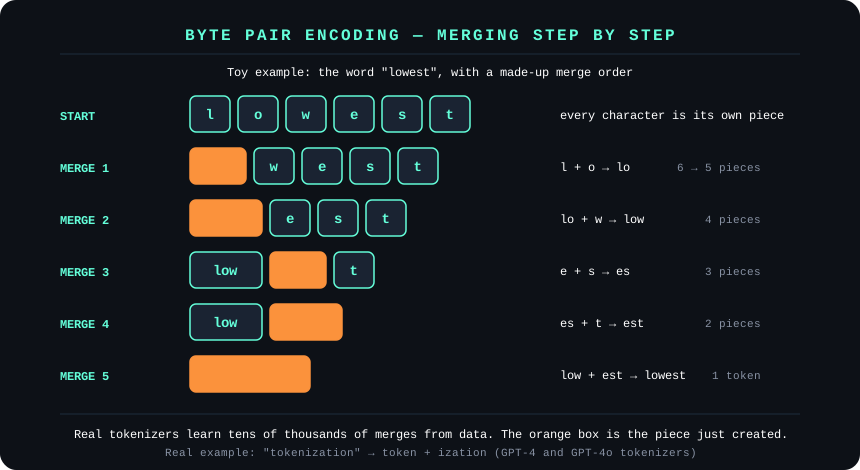
A word the tokenizer has seen a lot becomes one token. A word it has rarely seen stays in several small pieces. That is why rare words and odd strings cost more.
Two things follow from this. The list of pieces is locked in once the model is trained, so you can't change how a model splits your text. And you don't need to build any of this yourself. You only need to know it exists, so token counts stop feeling random.
GPT-4o uses a vocabulary called o200k_base (about 200,000 pieces), and older GPT-4 models use cl100k_base. The same sentence can have different token counts on different models, so don't reuse one model's count for another. Even within one family it can change. As of this writing, Anthropic says Claude 4.7 and every newer model (including the Claude 5 models, like the one in the counting example below) use a newer tokenizer that produces about 30% more tokens for the same text than Sonnet 4.6 and earlier (source).
SentencePiece: Splitting Text Without Spaces
Many tokenizers have a catch. They assume words are separated by spaces. That works for English, but not for Chinese or Japanese, which don't put spaces between words.
SentencePiece is a free tool from Google that avoids the problem. It doesn't try to find words first. It treats your text as one long line of characters and treats the space as just another character, shown as ▁. It can learn its pieces using BPE or a similar method.
Here is how it splits the same sentence in two languages:
SentencePiece puts the ▁ at the front of a word, and it pretends the text starts with a space, which is why the first word gets one too. In the Chinese example, the model keeps that starting space as a piece of its own, so you see a lone ▁ before 你. The Chinese pieces are real output from the mT5 model used in the demo below.
So which models use what? As far as the public documentation shows:
| Model | Tokenizer |
|---|---|
| GPT-3.5, GPT-4, GPT-4o | BPE (cl100k_base and o200k_base) |
| T5, mT5, Llama 2, Gemma | SentencePiece |
| Llama 3 | BPE, not SentencePiece |
| Gemini | Google's own tokenizer. Count with the API's count_tokens method |
| Claude | Anthropic's own tokenizer. It isn't published as a library, which is why the counting example below calls the API |
Try it below. This demo runs a real SentencePiece model: Google's multilingual mT5, trained on 101 languages. It isn't the tokenizer GPT or Claude uses, but it shows how a SentencePiece model splits different languages.
"Hello World"
▁ means a space came before the piece. So ▁World is " World". A lone ▁ is a space that got its own piece.
A tokenizer only knows the pieces it saw during training. If it mostly saw English, English words become single tokens while other languages get chopped into many small pieces, so the same meaning costs more. Training on a more balanced mix of languages helps, and that is what multilingual models like mT5 do. Even so, Korean still takes more tokens than English for the same meaning. In the demo above, click "English" and then "Korean" and compare the counts. Either way, measure with the tokenizer you actually use.
You won't build a tokenizer in day-to-day work. It matters when you pick a model for a multilingual product, because the tokenizer decides what each language costs.
The Context Window
The context window is the most text a model can handle in one request, measured in tokens. It's the model's short-term memory.
Everything counts toward it: your instructions, the chat history, any documents you attach, and the model's reply.
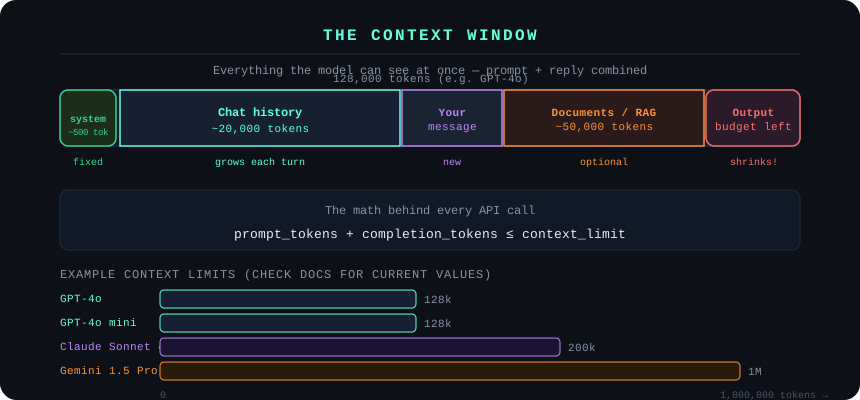
This catches a lot of beginners. A "128k context" model doesn't give you 128k tokens for your prompt. It gives you 128k for prompt + reply combined. If your prompt is 120k tokens, the answer has only 8k tokens of room left.
There is a second limit too: most models also cap the reply on its own, and that cap is usually far smaller than the window, often a few thousand to tens of thousands of tokens depending on the model. So you can't send a 1k-token prompt to a 128k model and get a 127k-token answer. Generation stops at the output cap long before the window is full. Check both limits in your provider's docs.
What happens if you go over
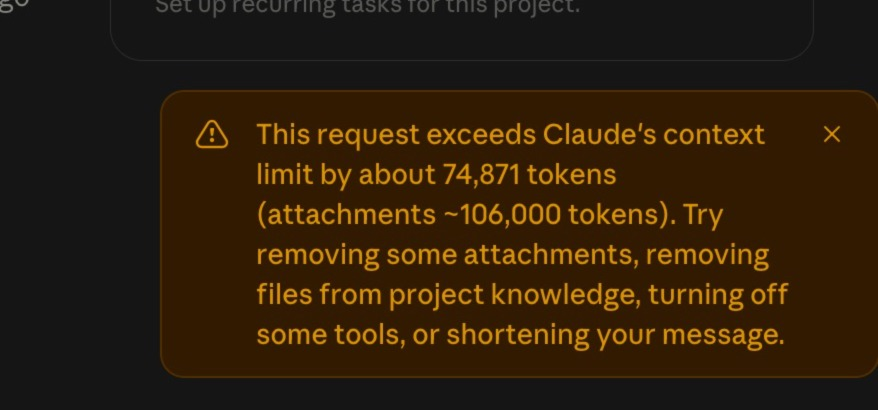
In a chat app, you get a message like this one from Claude. It reports how far over the limit the request is and which part, here the attachments, is taking up the space:
Through the API, the request is rejected with an error instead of being quietly cut:
The fix is to count tokens before you send. We'll do that in a moment.
Tokens Are Money
LLM providers bill by the token. Your text is tokenized, the tokens are counted, and the count is multiplied by a price per million tokens.
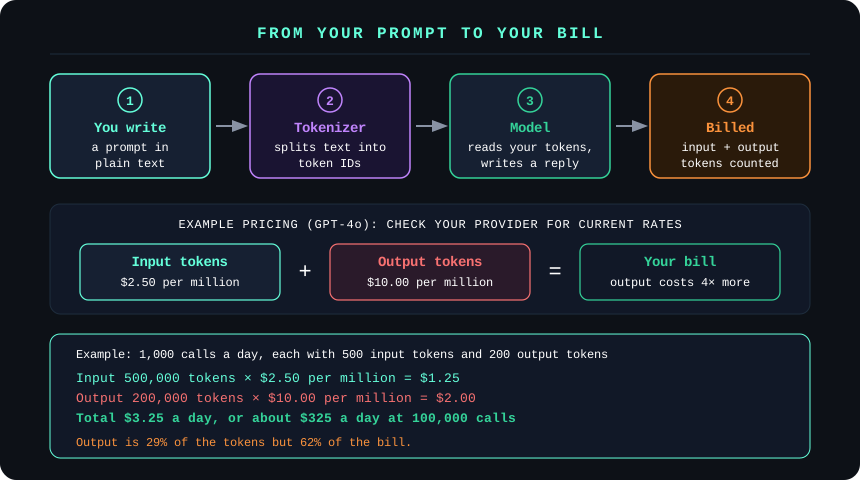
One detail surprises newcomers: output tokens usually cost more than input tokens, often several times more. The model reads your prompt in one pass, but it writes its reply one token at a time, and that's more work. Check your provider's pricing page for the exact ratio.
What this means in practice:
- If your app writes a lot (reports, summaries, code), output tokens will be most of your bill.
- If your app reads a lot and answers briefly (classification, short Q&A), input tokens will be most of your bill.
Counting Tokens in Code
Don't guess. Measure.
OpenAI models in JavaScript
OpenAI models in Python
In OpenAI's chat format, each message carries a few extra tokens of formatting that you never see, usually about 3–4. A 10-message conversation can add around 40 tokens you didn't write, so count the whole request, not just your text. Tools and function calling add much more: the tool definitions you send, plus the provider's built-in tool instructions, can cost hundreds of tokens per request, and they never appear in your visible prompt.
Claude (Anthropic SDK)
Anthropic's tokenizer isn't published as a standalone library, so ask the API to count for you. It uses the real tokenizer:
Use this to check an expensive request before you send it. Count with the same model you will call, because newer Claude models can produce different counts for the same text.
For a quick visual check without writing any code, paste text into the OpenAI Tokenizer. It colours each token, which is the fastest way to build intuition. Try a long word, a number, a sentence in another language and some indented code.
Gotchas That Cost Real Money
Numbers are expensive
Numbers don't repeat the way words do, so long ones often get split. OpenAI's tokenizers (the GPT-4 and GPT-4o ones used in this post) cut a number into chunks of up to three digits, starting from the left, and each chunk is one token. They do this on purpose, with a rule applied before the merging step. So 1000000000 (ten digits) becomes 100 + 000 + 000 + 0, which is 4 tokens. Other tokenizers behave differently: some split every digit separately, and others keep common numbers such as years whole. Here are real counts from the GPT-4 and GPT-4o tokenizers:
If you send big JSON payloads full of IDs, prices or coordinates, every digit adds up. Round, shorten or leave out numbers the model doesn't need.
Other languages often cost more
You saw this at the top of the post: one sentence took 8 tokens in English and 23 to 33 in Korean, Hindi and Thai on the GPT-4 tokenizer. Newer tokenizers have narrowed the gap but not closed it:
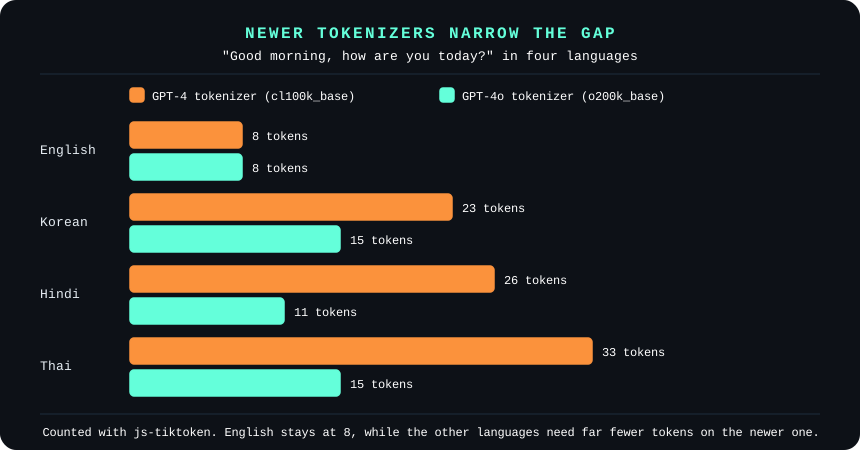
If you serve several languages, measure each one on the model you plan to use before you budget.
Extra whitespace in prompts
Blank lines and stray indentation in a prompt are sent with every request:
In this tiny example the messy version is 13 tokens and the clean one is 10, so 3 are wasted. One call won't notice, but at 10,000 requests a day that is 30,000 tokens a day, and real prompts carry far more padding. It's small money per day that adds up over a year for no benefit.
Patterns for Real Apps
Check the size before you send
Measure the prompt, leave room for the reply, and drop the oldest chat messages if you're over:
This is cheap protection against context_length_exceeded errors.
Split long documents at paragraphs
If a document is too big, split it into chunks. Cut at paragraph breaks, not at a fixed character count, so you don't slice sentences in half. This uses the countTokens helper from above:
A single paragraph longer than the limit stays in one chunk. If that matters, split it by sentences too.
Log usage on every call
Every response tells you how many tokens it used. Record that next to the feature that made the call:
After a week of logs, you'll know exactly which feature is eating your budget. (The prices in this snippet are examples. Use your provider's current rates.)
Best Practices to Use Fewer Tokens
You can't change how a model tokenizes text, but you control what you send and what you ask for back. The tips below follow the official guidance from Anthropic, OpenAI and Google. Provider docs and prices change, so check the linked pages before you rely on a number.
In a chat app
- Start a new conversation for a new topic. Every earlier message is sent again with each new one, so a chat that has wandered through three problems pays for all three every time. Claude's help centre gives the same advice in its usage limit best practices.
- Group related questions into one message, and put the background up front, so you need fewer back-and-forth turns.
- Paste only the relevant part. Share the section you're asking about instead of a whole document, log or email thread.
- Ask for the shape you want. "Summarise in three bullets" gets a shorter reply than an open question, and replies are the costly side.
- Remember that attachments count as tokens, as the context-limit warning above shows.
When you build with an API
1. Generate fewer output tokens. OpenAI's guidance is to ask the model to be concise and to set a maximum output length (max_completion_tokens in OpenAI's current API, called max_tokens in older versions) or stop sequences (strings that make the model stop writing when it produces them) so generation ends early. For structured output, shorter field names and less syntax also help.
2. Send fewer input tokens. Filter and prune context before it reaches the model: clean up retrieved documents, strip HTML, drop unused JSON fields and summarise old chat history.
3. Use prompt caching. If many requests start with the same long instructions or documents, the provider can reuse that shared beginning at a lower price. With the automatic, prefix-matching kinds, put the stable content first and the changing content last, because only an identical beginning is reused:
- Anthropic: add a
cache_controlfield, a setting that marks which part of your prompt to reuse. Cache reads cost about 0.1× the normal input price on most models, and writes cost more (1.25× for the default 5-minute cache). - OpenAI: automatic on supported models. Keep tool definitions and earlier messages unchanged so the shared beginning matches.
- Google Gemini: implicit caching is on by default for Gemini 2.5 and newer models. Explicit caching, available through the
generateContentAPI, lets you store a large item such as a long video or document once and refer to it in later requests, so the "stable content first" rule is less strict there.
Each provider sets a minimum prompt length for caching, so short prompts won't benefit. See the Anthropic, OpenAI and Gemini docs for the current rules.
4. Pick the right model for the job. Anthropic recommends its small model (Haiku) for simple tasks, its mid-size one (Sonnet) for most production work and its largest (Opus) for the hardest reasoning. OpenAI says the same about smaller models: they are usually faster and cheaper. Classification and extraction rarely need the biggest model.
5. Batch work that isn't urgent. Anthropic's Batch API gives a 50% discount on input and output tokens for asynchronous jobs (you submit them and collect the results later instead of getting an instant reply), and it can be combined with prompt caching. Check whether your provider offers something similar.
6. Watch the hidden tokens. Tool definitions, images, audio, video and a model's "thinking" (the extra reasoning tokens some models spend before they answer) all count toward usage. Gemini's docs, for example, list how many tokens an image or a second of audio uses and track thinking tokens separately.
7. Measure before and after. Count tokens before you send (Gemini has count_tokens, Anthropic has a token counting endpoint, OpenAI has tiktoken) and read the usage numbers in each response. Change one thing at a time and compare.
One Last Thing: Tokens Aren't Meaning
You might worry that splitting a word into pieces confuses the model. It doesn't. Tokens are just the entry point. The model quickly turns them into long lists of numbers, called embeddings, that capture meaning, and works from there, so token + ization is still understood as one idea.
What tokens control is your budget. When a provider says "200k context", it means 200,000 tokens, not characters or words. Whenever you plan a prompt, think in tokens.
Spotted a mistake or have a suggestion?
If something in this post is unclear, wrong or out of date, or you have an idea to improve it, tell me using the contact form.